Categories
Text Scanning

What Each of the 17 Characters in a VIN Tells You and How AI VIN Scanning Reads Them in Second

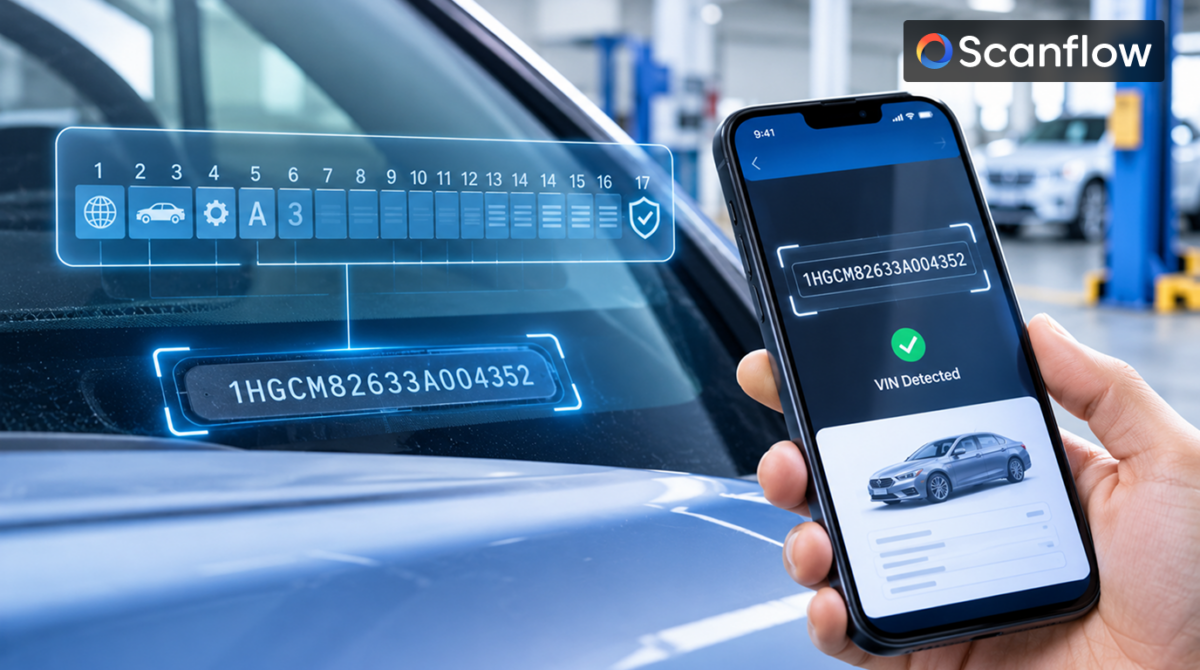
A VIN looks like a random string of letters and numbers stamped on a plate. It is actually a structured code and each of its 17 characters has a job. Once you know how it is laid out, you can read a lot about a vehicle before you ever open the door. This blog walks through what each part of a VIN tells you, why reading it accurately matters and how AI VIN scanning captures all 17 characters in seconds without anyone typing them. 

The Three Blocks of a VIN 

A VIN can be split into three blocks. The first block says who built the vehicle. The second describes the vehicle itself. The third is the part that makes it unique. The layout below follows the common standard and the details can vary a little by region and manufacturer. 

Characters 1 to 3, who made it. These characters form the manufacturer identifier. The first character usually points to the country or region where the vehicle was built. The second identifies the manufacturer. The third points to the vehicle type or the manufacturer’s division. Together they answer a simple question: which company built this, and where? 

Characters 4 to 8, what it is. This block describes the vehicle. It typically covers details such as the model, body style, engine type, and sometimes safety equipment. The exact meaning of each position is set by the manufacturer, so the same character can mean different things on different brands. This is why a VIN needs a decoding source behind it, not just a person who knows the code. 

Character 9, the check character. In North America, the ninth character is a check digit. It is worked out from the other characters using a fixed formula, so that a VIN with a mistyped or misread character can be spotted because the numbers no longer add up. Not every market uses this rule in the same way, but where it applies it is a built-in safeguard. 

Character 10, the model year. One character records the model year. The codes use a mix of letters and numbers and they repeat after a long cycle, so the year is read together with other clues about the vehicle. 

Character 11, the assembly plant. This character shows which plant the vehicle came from. For a manufacturer with several factories, it narrows down where the car was built. 

Characters 12 to 17, the serial number. The last six characters are the production sequence. They separate one vehicle from every other vehicle built with the same specification. This is the part that makes the VIN unique. 

One more rule is worth knowing. VINs do not use the letters I, O, and Q, because they are too easy to confuse with the numbers 1 and 0. 

Why Reading Them Accurately Matters 

Each block feeds a decision. The manufacturer block helps confirm that a vehicle is what it claims to be. The description block drives which parts, specifications, and service procedures apply. The year and plant help with warranty and recall questions. The serial number ties everything to one specific car. 

The trouble is that a single wrong character can send the whole lookup in the wrong direction. A transposed digit in the serial section points to a different vehicle. A mistake in the description block can return the wrong engine or trim. Manual VIN entry is where compliance risk starts, because a person copying 17 characters from a plate, often under time pressure, will sooner or later get one wrong. 

Where the Characters Are Hard to Read 

The VIN appears in several places on a vehicle. A plate sits on the dashboard, visible through the windshield. A label on the door frame carries it too. It may also be etched on the chassis or on the windshield, and printed on documents. Each location has its own problems. Dashboard plates sit behind glass, with glare and reflections. Door labels get scuffed. Etched numbers have low contrast. Curved surfaces distort the characters. None of that helps a tired eye. 

How AI VIN Scanning Reads All 17 Characters 

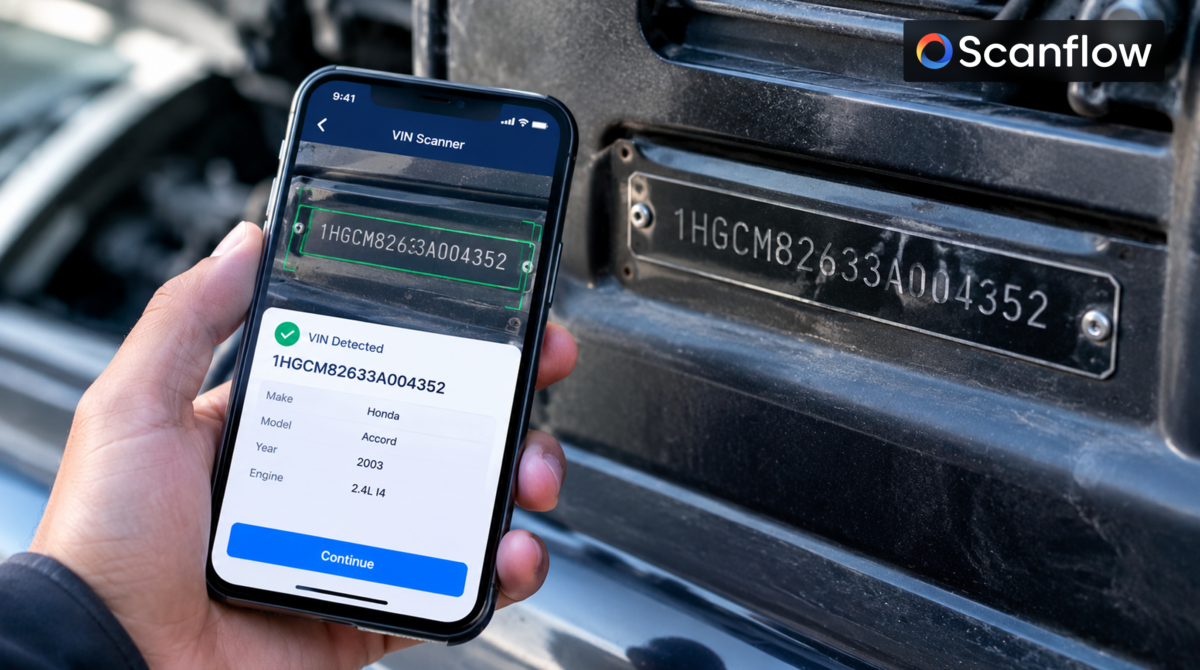
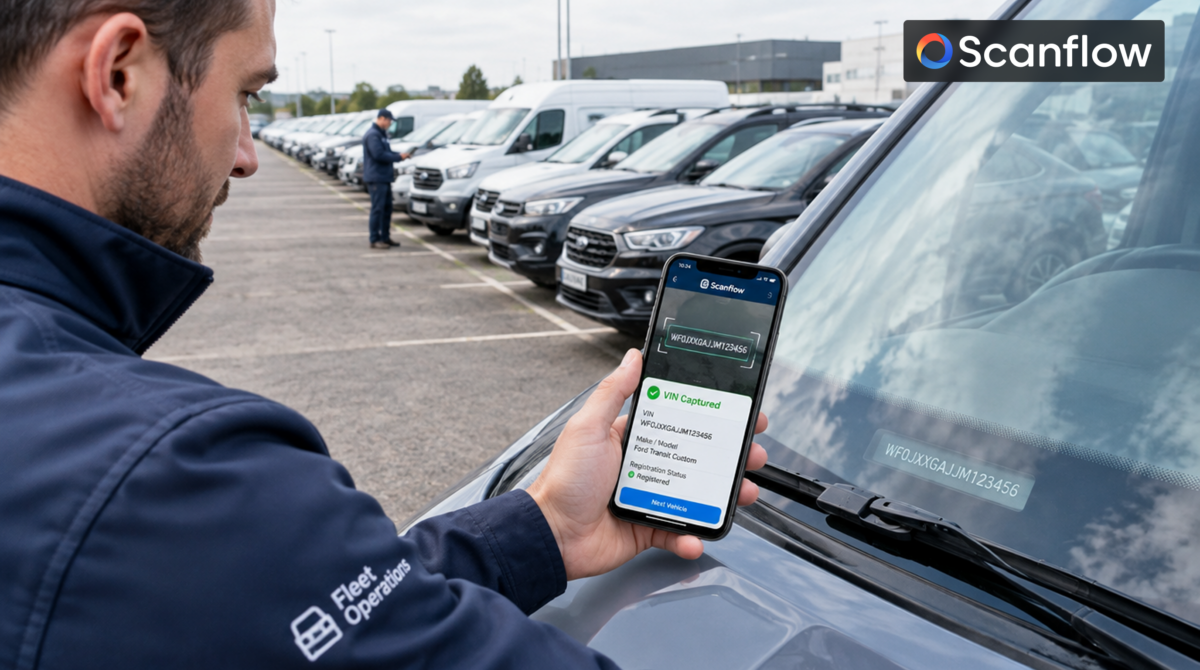
AI VIN scanning replaces reading and typing with a camera. A person points a phone at the VIN and the software captures the characters directly. Scanflow’s VIN scanning reads VIN barcodes, etched chassis numbers, dashboard stickers, and door jamb labels, even in glare, low light, or on curved surfaces and it also reads windshield serials. It works with any smartphone camera, so there is no dedicated hardware to buy and it is built to handle damaged labels, poor lighting, and non-standard printing. 

Because the VIN is text, the same tool can handle VIN text capture as well as barcodes. Whichever form the VIN takes on a given car, the team can capture it the same way. 

From 17 Characters to Vehicle Information 

Capturing the characters is the first step. The software then decodes the 17-digit VIN serial code and returns structured vehicle identity data. With instant VIN decode to vehicle specs, the person scanning can see what the VIN says the vehicle is, and check it against the car in front of them. Scanflow describes the result as verified vehicle identity data that can be pushed to a DMS, fleet platform or CRM. 

What gets returned depends on the decoding source behind the scan, so it is worth asking any provider which fields you will receive. The decode is only as useful as the data it is matched against. 

Using the Check Character 

The check character offers another advantage for any decoding system. Because it is calculated from the other 16 characters, software can use it to flag a VIN that does not add up, which suggests a misread or a mistyped number. Whether a particular tool applies this check is worth confirming, since it is a simple way to catch errors early. 

A Simple Example of Why Position Matters 

The same slip can do very different damage depending on where it lands. A wrong character in the first three positions can point to the wrong manufacturer. A wrong character in the description block can change the engine or trim that comes back from a lookup. A wrong character in the last six positions can match a different car altogether. Because the damage depends on position, it is hard for a person to judge which mistakes are harmless. The safer approach is to avoid typing the code at all. 

Speed and Offline Use 

Scanning takes seconds, which is what makes it practical on a busy lot or line. In areas with poor signal, VIN data is scanned and inferred on-device, so the work continues without a connection and syncs later. That matters for yards, auction lanes and workshops where signal is uneven. 

What a VIN Does Not Tell You 

It is also worth being honest about the limits. A VIN identifies a vehicle and describes how it was built. It does not tell you the car’s condition, its accident history, who owns it, or whether the plate has been tampered with. Those answers come from history reports, inspections, and official records. Scanflow’s page states 99 percent or better scan accuracy, which is a vendor claim worth testing on your own vehicles. 

So, What Is the Takeaway? 

Seventeen characters carry the manufacturer, the vehicle description, a built-in check, the year, the plant, and a unique serial number. That is a lot of information, and all of it depends on the characters being captured correctly. AI VIN scanning removes the weakest step, the human typing and gives teams a clean, repeatable reading of every vehicle they handle. 
#VINScanning #VINDecoder #VehicleIdentification #VehicleData #AutomotiveAI #ComputerVision #AutomotiveIndustry #DataAccuracy #AssetIdentification #DealershipTech #FleetManagement #AutomotiveQuality #SmartScanning #VehicleTraceability #AutomotiveTech #DigitalTransformation #AIinAutomotive #VehicleInspection #B2B #AutomotiveOEM 

Categories
label capture

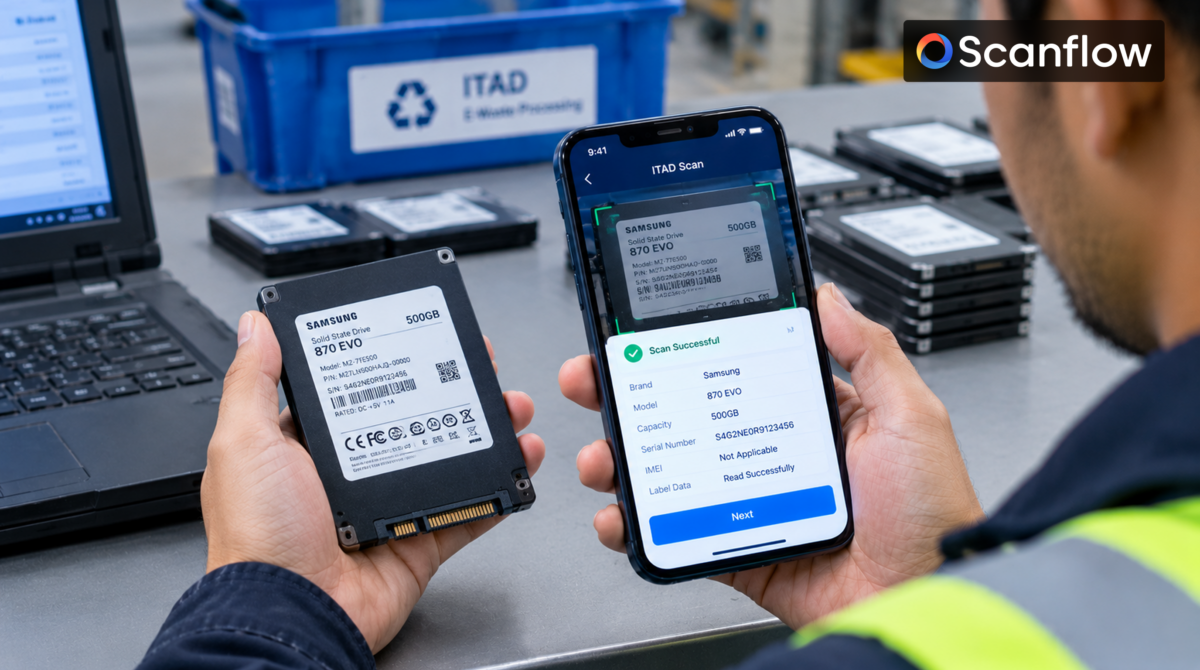
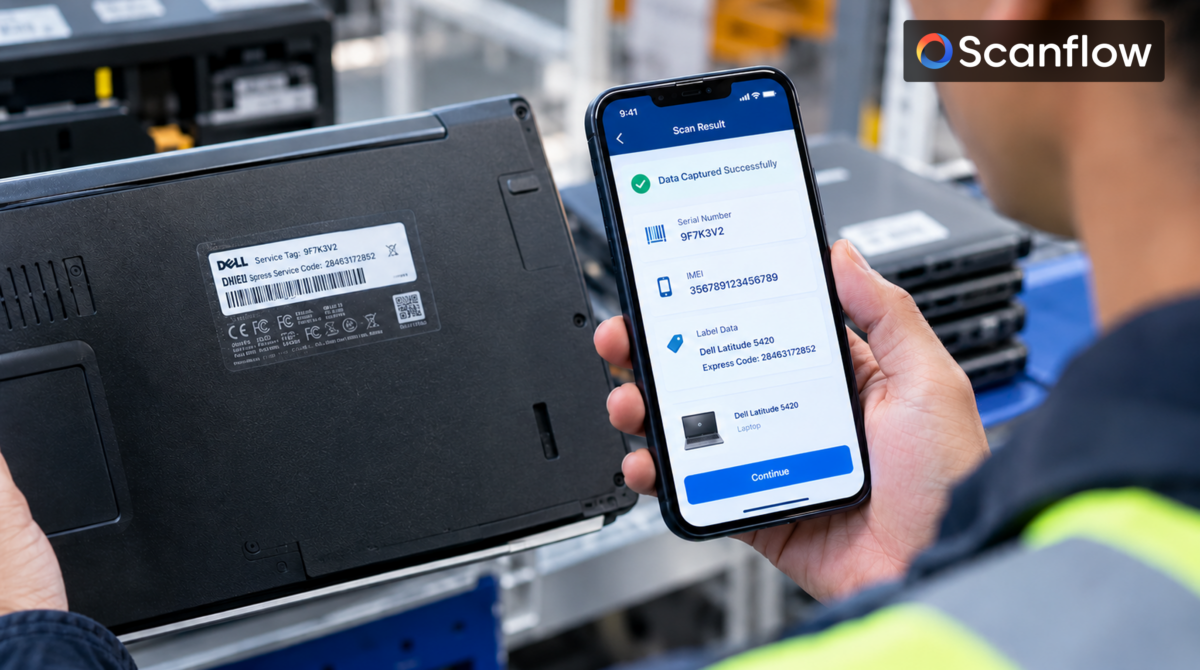
How to Capture Serials, IMEIs and Label Data in One Scan

Serial Number Scanner: How to Capture Serials, IMEIs and Label Data in One Scan

Key takeaways

  • A serial number scanner uses a camera and OCR or barcode decoding to read a product’s serial number instead of typing it.
  • Most device labels carry several identifiers at once: serial, IMEI, model, part number and one or more barcodes.
  • Barcode-only scanners miss labels with no barcode or a damaged one. Single-line OCR reads one field and misses the rest.
  • Label capture reads barcodes and printed text together and returns each field your app needs.
  • The best SDK for the job handles worn, small, curved and low-contrast labels, not just clean ones.

What Is a Serial Number Scanner?

A serial number scanner is software that reads a product’s unique serial number from a label or part using a camera, then sends it to an app or system. It replaces typing long strings of letters and numbers by hand.

Serial number scanners work in two ways. Some decode a barcode or QR code that encodes the serial. Others use optical character recognition (OCR) to read the printed characters directly. The most useful ones do both.

Why Serial Numbers on Labels Are Hard to Read

Serial numbers look simple on a spec sheet. On a real device in a warehouse or service van, they are some of the hardest text to capture.

Where the serial isWhat's usually on itWhat makes it hard
Laptop and server labelsSerial, model, part number, barcode(s), regulatory marksSmall print, many look-alike fields, faded after years of use
Phone and tablet boxes or traysSerial, IMEI 1, IMEI 2, model, colour, storageSeveral barcodes side by side, glossy surfaces
Hard drives and SSDsSerial, model, capacity, firmware, barcodeTiny labels, reflective metal, scratches
Industrial equipment nameplatesSerial, model, rating dataStamped or engraved metal, low contrast, curved surfaces
Returned or used devicesAny of the aboveTorn, smudged or partially missing labels

The common thread is that the serial is never alone. A scanner has to find the right field among several, and still read it when the label is worn.

Barcode Scanning vs OCR vs Label Capture

There are three ways to capture a serial number from a label. They solve different problems.

MethodHow it worksGood forBreaks when
Barcode scanningDecodes the barcode that encodes the serialClean labels with one known barcodeThere's no barcode, it's damaged, or several barcodes sit side by side
Single-line OCRReads one line of printed textA single serial printed on its ownThe label has many fields, or the serial must be matched to its IMEI or model
Label captureReads barcodes and printed text together, then picks out each fieldMulti-field labels: serial + IMEI + model + part number

For most operations, the question is not “can it read a serial?” but “can it read every field I need from this label in one go?” That is what label capture is built for. For background on barcode formats, see our guide to types of barcodes.

Where Teams Scan Serial Numbers Every Day

Serial number capture sits at the start of many workflows. If it is wrong there, every record after it is wrong too.

  • ITAD intake: every laptop, phone and drive is logged by serial on arrival. That serial links to its erasure record, grade and final disposition the backbone of an R2v3 chain of custody.
  • Electronics retail and returns: serial and IMEI are captured at sale and at return to stop fraud and process warranties.
  • Field service: technicians record the serial of the unit they repair, often on equipment in awkward, dim places.
  • Warehouse and 3PL: serialised stock is scanned at receiving, picking and shipping for traceability.
  • Manufacturing and assembly: part serials are recorded so a finished product can be traced back to its components.

What to Look for in a Serial Number Scanner SDK

If you are adding serial number scanning to your own app, test SDKs on your hardest labels, not on clean demo samples. Check these six things:

  1. Multi-field capture. Can it return serial, IMEI, model and barcode values from one scan, each labelled?
  2. Format rules. Can you define the pattern a serial should follow, so a misread is flagged instead of saved?
  3. Hard surfaces. Does it read worn, small, glossy, curved and low-contrast labels, including stamped metal?
  4. Barcode + text together. Does it fall back to printed text when a barcode is damaged, or cross-check one against the other?
  5. Platform fit. Native iOS and Android support, and how it fits into your existing app.
  6. Data handling. Where images and results are processed and stored, to match your security needs.

How Scanflow Label Capture Works

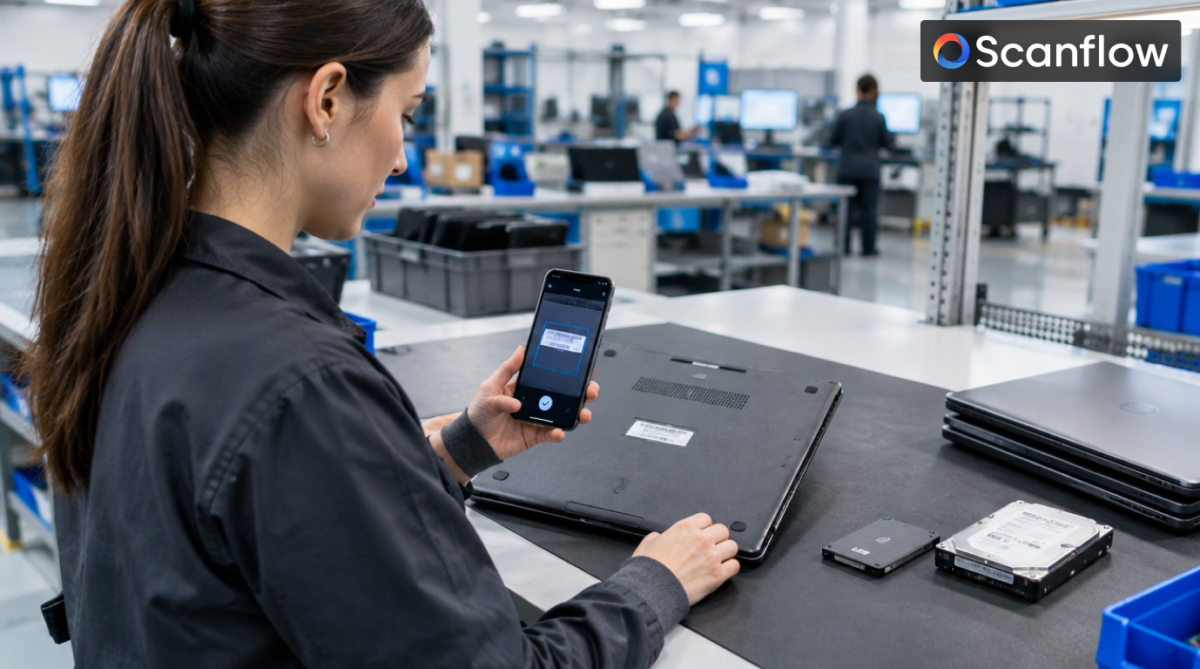
Scanflow Label Capture is part of Scanflow Capture, an AI-enabled asset identification SDK for iOS and Android. It reads barcodes and printed text on a label in a single capture and returns the fields your workflow needs.

A typical flow looks like this:

  1. The user points a phone or tablet at the label.
  2. The SDK finds the barcodes and text blocks on the label.
  3. It identifies the fields you configured, such as serial number, IMEI, model and part number.
  4. It returns each value to your app, ready to save against the asset record.

Scanflow is built for the identifiers ordinary scanners struggle with: damaged labels, low-contrast and stamped serials, and labels with many fields. The same SDK also covers serial number and text scanning, VIN scanning and tire sidewall scanning, so one integration handles several identification jobs.

Categories
ITAD

What ITAD Auditors Check and Why It Comes Down to the Serial Number

R2v3 Certification: What ITAD Auditors Check and Why It Comes Down to the Serial Number

Key takeaways

  • R2v3 is the current version of the R2 Standard for electronics reuse and recycling, run by SERI (Sustainable Electronics Recycling International).
  • It has 10 core requirements that apply to every certified facility, plus appendices that apply based on what the facility does.
  • Any facility that erases data with software must also be certified to Appendix B, Data Sanitization.
  • Auditors check whether any device can be traced, by serial number, from intake to final disposition.
  • Most chain-of-custody gaps start at intake, when serials are typed by hand or not captured at all.

What Is R2v3 Certification?

R2v3 certification shows that an electronics reuse, repair or recycling facility meets the R2 Standard, version 3, for environmental, health, safety and data security practices. The standard is owned by SERI and facilities are audited by accredited third-party certification bodies.

For ITAD (IT asset disposition) companies, R2v3 has become a baseline customers ask for. Enterprise buyers, especially in regulated sectors, often require it before they hand over retired laptops, servers and phones.

The 10 R2v3 Core Requirements

Every R2v3 facility must meet all 10 core requirements. Appendices are added on top, depending on the services the facility offers.

Core requirementWhat it covers
1. ScopeWhich facility, processes and equipment the certification covers
2. Hierarchy of Responsible Management StrategiesPrioritising reuse and recovery over disposal
3. EH&S Management SystemEnvironment, health and safety controls
4. Legal and Other RequirementsCompliance with applicable laws, including export rules
5. Tracking ThroughputTracking equipment and materials in, through and out of the facility
6. Sorting, Categorization and ProcessingSorting incoming equipment into the right streams
7. Data SecurityA data sanitization plan with security controls for every data device
8. Focus MaterialsSafe handling of materials such as batteries, mercury and CRTs
9. Facility RequirementsPhysical site, security and closure planning
10. TransportSafe, secure transport of equipment and materials

The appendices cover specific activities. They include Appendix A (Downstream Recycling Chain), Appendix B (Data Sanitization), Appendix C (Test and Repair) and Appendix D (Specialty Electronics Reuse), among others.

Core 7 vs Appendix B: Which Applies to You?

Core 7 applies to every R2v3 facility. Appendix B applies if your facility performs logical sanitization erasing data with software so the device can be reused.

  • Physical destruction only (shredding, crushing, disintegrating) using a NIST SP 800-88 method: Core 7 can cover it, and Appendix B is not required.
  • Software erasure for reuse or resale: Appendix B certification is required.

Most ITAD operators that refurbish and resell devices therefore need Appendix B. That brings stricter requirements for sanitization records — which is where serial numbers become critical.

What R2v3 Auditors Check

Auditors want proof, not policy. The core test is simple: pick any device, and show its full history.

In practice, that means an auditor can choose a serial number from a customer manifest, a sanitization log or a sales record, and expect you to show:

  1. When and from whom it was received.
  2. Where it was stored and who handled it.
  3. How its data was sanitized, with what method, and whether it was verified.
  4. Its test and grade result, if it was refurbished.
  5. Where it went: resale, a downstream recycler, or destruction.

If the serial on the intake record doesn’t match the serial on the erasure certificate, the trail breaks. One mismatch can turn into a finding.

What a Data Destruction Certificate Should Include

A data destruction certificate is the record that proves a specific device’s data was sanitized. SERI’s recommended record fields are modeled on NIST SP 800-88, the U.S. guideline for media sanitization. NIST published Revision 2 of SP 800-88 in September 2025.

A strong certificate, issued per device, records:

FieldWhy it matters
Device manufacturer and modelIdentifies the device type
Serial numberTies the record to one physical device the field auditors match on
Media type and serial (for drives)Ties the record to the storage itself
Sanitization method and toolShows what was done (e.g. clear, purge, destroy)
Verification resultProves the method worked
Date and timePlaces it in the chain of custody
Technician or workstationShows who performed it

Batch certificates that say “200 laptops destroyed” without a serial for each are a common audit gap.

Where Chain of Custody Breaks

Most erasure and destruction tools record serials automatically once the device is on the bench. The weak point is earlier: intake and receiving.

  • Typed serials. Technicians key in 10–20 character serials from small, faded labels. Look-alike characters (0/O, 1/I, 8/B) cause mismatches later.
  • Devices that won’t boot. Dead or locked devices can’t report their own serial, so it must be read off the label.
  • Loose drives. Drives pulled from devices need their own serials captured and linked to the parent asset.
  • Spreadsheet manifests. Manifests that list counts instead of serials can’t be reconciled line by line.

Every one of these happens before sanitization software ever touches the device. If intake is wrong, every later record inherits the error.

How Serial-Level Capture Keeps You Audit-Ready

The fix is to capture the serial correctly at the first touchpoint, from the label, and use that same record at every step after.

Scanflow ITAD serial number scanning is part of Scanflow Capture, an AI-enabled SDK for iOS and Android. It lets ITAD teams scan serial numbers, model numbers and barcodes from device and drive labels with a phone or tablet, inside the apps they already use.

For an ITAD operator, that means:

  • Intake by scan, not by typing – including devices that won’t power on.
  • Multi-field labels in one capture – serial, model and barcode together, using serial number scanner and label capture.
  • Drives linked to their parent device at the moment they are pulled.
  • One clean serial that intake, erasure, grading and dispatch records can all match.

Scanflow does not certify facilities or replace erasure software. It makes the first record in the chain correct, so the rest of the chain can be proven.

Categories
vin scanning

Why One Wrong VIN Digit Can Cost You a Used Car Auction Deal and How Mobile VIN Scanning Fixes It

Picture an auction lane on a busy sale day. Cars roll through one after another, each with a few seconds in front of the buyers. Behind the scenes, someone has already typed the VIN of every car into the system. One of those entries has a single wrong character. Nobody notices. The listing goes live with the specs of a different vehicle, a buyer bids on what the screen says and the problem only appears after the sale, when the car in the yard does not match the car on the paperwork. This is how one wrong VIN digit can cost an auction deal. 

This blog looks at why a single wrong character matters so much, how it creeps in at auctions and how mobile VIN scanning removes the typing step that causes it. 

Why One Digit Matters 

A VIN is 17 characters and almost every character carries meaning. The first few identify the manufacturer and region. Others describe the model, body style and engine. One position records the model year and the rest identify the individual car. In many markets, including North America, one position is a check character that is calculated from the others so that a mistyped VIN can be spotted. 

Change one character and the story changes. The decoded model, year, trim, or engine can come out wrong. The VIN may fail validation. Or it may happen to match a different real vehicle, which is worse, because the system accepts it without complaint. In either case, the listing no longer describes the car it is attached to. 

How Wrong Digits Get In at Auctions 

Auctions are high-volume, fast, and messy, which is exactly where typing mistakes thrive. A consignment team may handle hundreds of vehicles in a day. VIN plates sit behind dirty windshields, with glare in daylight and shadow at the edge of a lot. Door labels get scuffed. Characters that look alike, such as a zero and the letter O or a one and the letter I, are easy to confuse by eye. VINs do not use the letters I, O and Q, but a tired person still has to work out which one they are looking at. 

Handwritten sheets add another step. A number gets copied from a plate to a sheet, then from the sheet to a system, sometimes by a different person. Each copy is a new chance for a slip. 

What a Wrong Digit Costs 

For a seller, the first cost is a listing that describes the wrong vehicle. A buyer who bids on a certain trim and engine and then finds something different will ask for a price adjustment, raise a dispute or walk away. The sale gets delayed while someone investigates and the car sits on the lot. 

For a buyer, the risk is paying for the wrong thing. A history report ordered on a mistyped VIN returns the history of another car or nothing at all. Decisions about price and condition get made on information that does not belong to the vehicle. 

There are paperwork costs too. Title and registration depend on a correct VIN and an error found late can hold up the transfer. Beyond the direct cost, repeated mismatches damage trust in the auction’s data. Buyers who cannot rely on the listing start to discount every car on the lane. 

How Mobile VIN Scanning Fixes the Typing Step 

The simplest fix is to stop typing. Mobile VIN capture lets a team point a phone at the VIN plate, chassis or windshield sticker and have the software read it. Scanflow’s mobile-first VIN barcode reader works with any smartphone camera, so there is no dedicated hardware to buy or maintain. It handles damaged labels, poor lighting and non-standard printing, which is exactly what a real lot looks like. 

The scan reads more than one kind of marking. Door-frame VIN barcode scanning, etched chassis numbers, dashboard stickers and windshield serials are all supported, so the team can capture the VIN from whichever location is clearest on that particular car. 

From Scan to Listing 

After the scan, the software decodes the 17-digit VIN serial code and returns structured vehicle identity data. With instant VIN decode to vehicle specs, the person at the lane can see straight away whether the decoded make, model and year match the car in front of them. If they do not, the problem is caught at check-in, when it takes seconds to fix, not after the sale. 

The same record can be pushed to the DMS or auction platform, so the listing starts from the correct data instead of a number someone typed. Scanflow describes this intake process as reliable across glare, low light and high-volume intake lanes, which fits the conditions at a busy sale. 

Working Anywhere on the Lot 

Auction yards are large and signal can be patchy between rows. VIN data is scanned and inferred on-device, so scanning continues without a connection and records sync automatically once the phone is back online. The SDK does not store any data on the device, which is a useful point for teams with data handling rules. 

Where It Fits in the Auction Flow 

Mobile scanning can be used at several points. At consignment, when a seller’s vehicle is checked in. At the lane, to confirm the car matches its listing before it runs. At buyer inspection, so a buyer can scan the VIN on a car they are considering and compare it with the listing. And in the transport yard after the sale, to confirm the right car is loaded for the right buyer. Scanflow notes that scanning at dealership intake can significantly reduce lot walk audit times, and the same logic applies to auction yards counting and checking large numbers of cars. 

What Buyers Gain

Scanning helps the buying side as much as the selling side. A dealer or independent buyer walking a lot can scan the VIN of any car they are interested in and see the decoded specs on their phone, then compare them with the listing. If the engine, trim, or year differ, they know before they bid. They can also scan the same VIN again when the car arrives at their own lot, which gives them a clean starting record instead of one copied from a sheet. Over time, buyers who see matching data on every lane are more willing to bid with confidence. 

Being Realistic About What It Fixes 

Scanning removes the typing error, not every risk. A correct VIN does not tell you the car’s condition, title status or whether the number has been tampered with, so a history report and an inspection are still needed. And if the seller provides the wrong paperwork, a scan will confirm the number on the car but not fix the document. Scanflow’s page states 99 percent or better scan accuracy, which is a vendor figure worth testing on your own lanes before relying on it. 

A Simple Routine to Start With 

A small change goes a long way. Scan every VIN at check-in instead of typing it. Compare the decoded specs with the car and the listing before the sale. Save every scan so there is a record of what was read and when. And agree who handles a mismatch so it is resolved quickly. 

So, Can Mobile VIN Scanning Save the Deal? 

It will not save every deal, but it removes one of the most avoidable reasons a deal goes wrong. A single digit costs almost nothing to get right when a camera reads it, and a lot to get wrong when a person types it. For auctions that depend on trust in their data, that is a small change with a clear payoff. 


#VINScanning #UsedCarAuction #AutoAuction #MobileScanning #DealershipTech #AutomotiveRetail #VehicleData #DataAccuracy #AutomotiveAI #ComputerVision #UsedCars #VehicleInspection #AutomotiveIndustry #AssetIdentification #SmartScanning #DigitalTransformation #VehicleRemarketing #B2B #AutomotiveTech #DealerOperations 

Categories
Tire Sidewall

Tire Date Code: How to Read It, Where to Find It and How Tire Shops Check Tire Age at Scale

Key takeaways

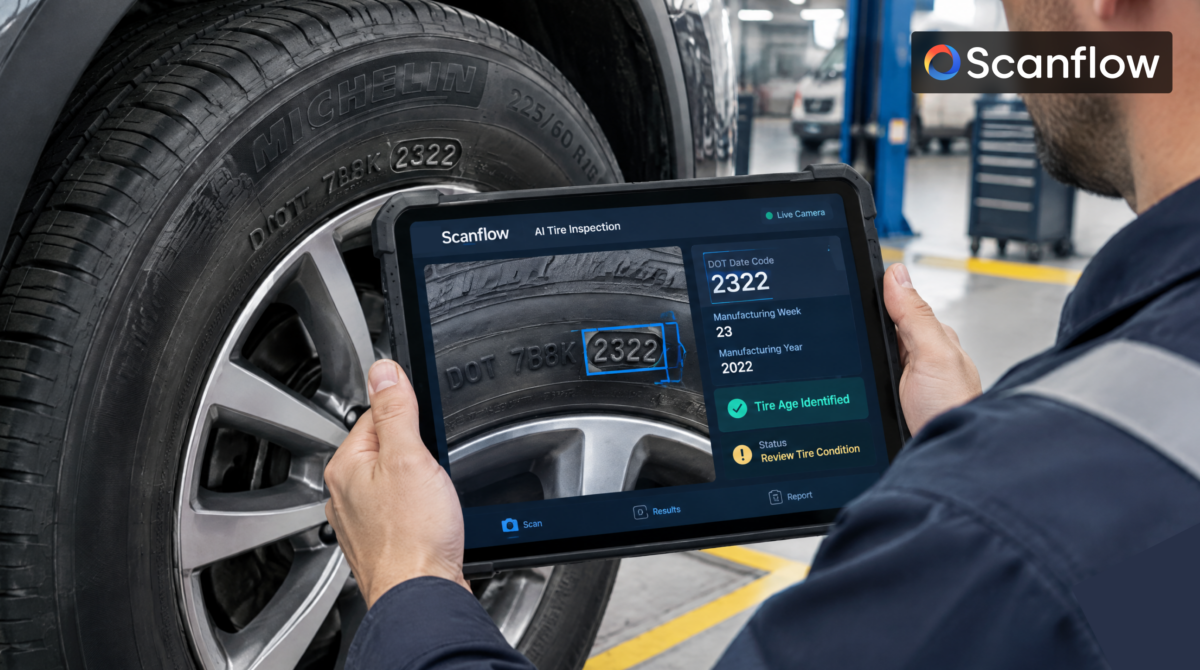
  • The tire date code is the last four digits of the DOT number on the sidewall. The first two digits are the week, the last two are the year.
  • “2421” means the tire was made in the 24th week of 2021.
  • A three-digit date code means the tire was made before 2000.
  • The full date code is often on only one sidewall, which may face inward once the tire is mounted.
  • Tire shops check date codes for safety, recalls, warranty and resale. Typing them by hand is slow and error-prone; AI-enabled smartphone scanning captures them in a single photo.

What Is a Tire Date Code?

A tire date code is the four-digit number at the end of a tire’s DOT code that shows the week and year the tire was manufactured. It is part of the Tire Identification Number (TIN), which U.S. federal rules require on every tire sold in the United States.

The full DOT code starts with the letters “DOT” and runs to roughly 10–13 characters. Only the final four digits carry the date. Everything before them identifies the factory, the tire size and the manufacturer’s own batch or type code.

How to Read a Tire Date Code

Read the date code in two pairs: the first two digits are the week of the year (01–52), and the last two are the year.

Example DOT codeDate codeWhat it means
DOT U2LL LMLR 24212421Week 24 of 2021 (mid-June 2021)
DOT 4B3X 9KF2 03190319Week 3 of 2019 (mid-January 2019)
DOT ATL2U 4AVA 52235223Week 52 of 2023 (late December 2023)
DOT XX 1234 48948948th week of a year in the 1990s — pre-2000 tire

A full DOT code breaks down into four parts:

  1. Plant code (2–3 characters after “DOT”) – the factory that made the tire.
  2. Size code (2 characters) – the tire size.
  3. Manufacturer’s code (up to 4 characters, optional) – type, brand or batch details.
  4. Date code (last 4 digits) – week and year of manufacture.

If the code ends in three digits, the tire was made before 2000. There is no reliable way to tell which year of the 1990s it was, and it should be treated as too old for service.

Where to Find the Date Code on a Tire

Look on the lower sidewall, near the rim, for a string that starts with “DOT”. The date code sits at the end of that string, often inside a small raised oval.

Three things make it harder to find than it should be:

  • One-sided placement. The full code, including the date, is often molded on only one sidewall. If you see a DOT code with no four-digit ending, check the other side.
  • Mounted tires. On a vehicle, the full code may face inward toward the suspension. You may need to turn the wheel or lift the vehicle.
  • Black-on-black text. The characters are embossed rubber on rubber, with no colour contrast. Dirt, tire shine and wear make them harder to read, especially in a dim service bay.

How Old Is Too Old? Tire Age Guidelines

There is no single U.S. federal age limit for passenger tires. Most guidance comes from tire and vehicle manufacturers and it varies by brand.

Common industry practice is:

  • Around 5 years: have tires inspected every year, even if tread looks fine.
  • Around 6 years: several vehicle manufacturers advise replacement from this point.
  • 10 years: widely treated as the outer limit, regardless of tread depth or appearance.

Rubber ages even when a tire sits unused in a warehouse or on a spare. Heat, sunlight and low inflation speed that up. Always follow the specific manufacturer’s guidance for the tire in front of you.

Why Tire Shops Check the Date Code on Every Tire

For a tire shop, dealership service lane or used-tire reseller, the date code is not trivia. It drives four everyday decisions:

  1. Safety and liability. Selling or re-mounting an aged tire exposes the shop if that tire fails.
  2. Recalls. Recalls are issued against specific DOT code ranges. Without the code on file, the shop cannot tell a customer whether their tires are affected.
  3. Warranty and registration. Warranty eligibility and tire registration both depend on the TIN being recorded correctly at the point of sale.
  4. Inventory and resale value. Older stock should sell first, and used or reconditioned tires are priced partly on age. A wrong date means a wrong price.

The common thread: every decision depends on the DOT code being captured accurately, for every tire, every time.

The Problem With Logging DOT Codes by Hand

Most shops still record DOT codes the slow way. A technician kneels, finds the code, reads embossed characters, and types or writes 10–13 characters per tire. A set of four means four times the effort, plus the inward-facing sidewall problem.

This creates predictable failures:

  • Transposed characters. Look-alike characters such as 8 and B, or 0 and D, slip into records.
  • Skipped tires. Under time pressure, technicians log one tire and assume the set matches.
  • Records that don’t connect. Codes written on paper rarely reach the inventory, invoice or registration system.

Each of these breaks the chain that recalls, warranties and audits rely on.

How Smartphone DOT Scanning Works

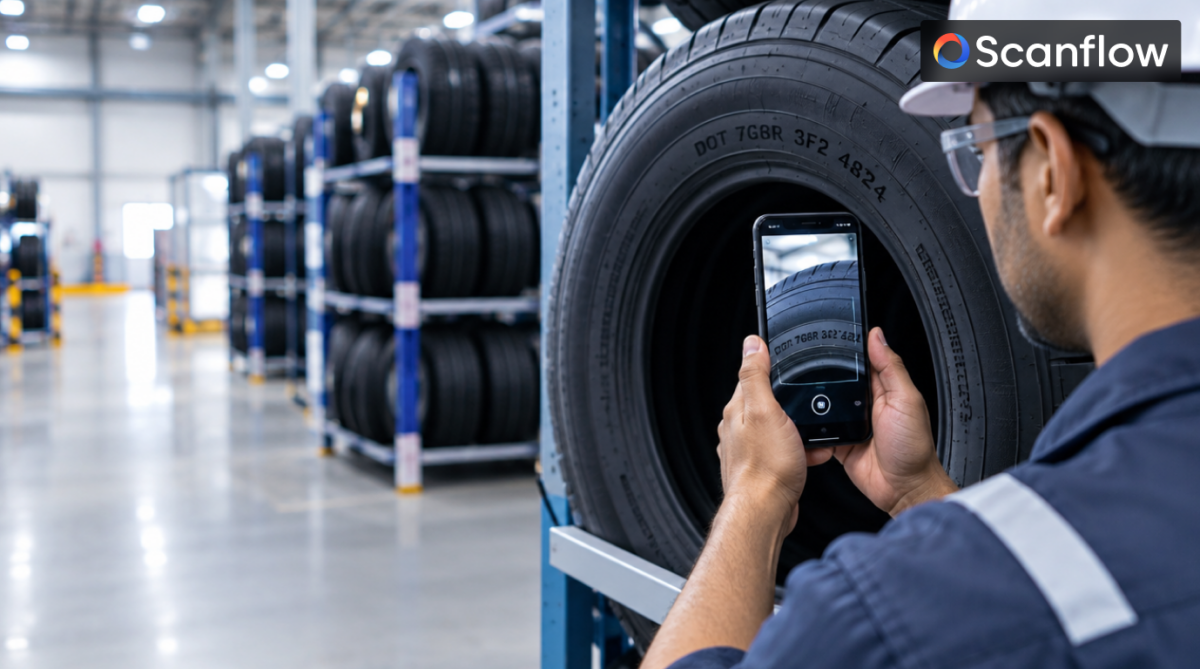
AI-enabled DOT scanning replaces manual typing with a single photo. A technician points a smartphone or tablet at the sidewall, and the app reads the full DOT code  including the date code  and sends it straight into the shop’s system.

The Scanflow tire sidewall scanning SDK is built for exactly this surface: embossed, low-contrast, black-on-black text on a curved sidewall. It plugs into existing iOS and Android apps, so shops and software vendors add DOT capture to the tools technicians already use, without new hardware.

For aftermarket and retail teams, that means:

  • Capture at intake, tire by tire, with the date code checked against the shop’s age policy on the spot.
  • Recall and registration data recorded at the point of sale instead of retyped later.
  • Inventory rotation based on real manufacture dates, not guesswork.
  • Used and reconditioned tire grading with age captured in the same workflow as tread checks.

For a step-by-step look at the capture itself, see how to scan tire DOT numbers with a smartphone.

Categories
Quality control

Casting Defects: 12 Types, Their Causes, Remedies and How to Detect Them on Every Part

Key takeaways

  • Casting defects are flaws formed while molten metal fills, cools and solidifies in a mould. Forging defects form while metal is shaped under pressure.
  • The most common casting defects are porosity, blowholes, shrinkage, cold shuts, misruns, hot tears, inclusions, flash and mould shift.
  • Most defects trace back to four root causes: gas, metal temperature, mould or core quality, and gating design.
  • Optical inspection catches surface-visible and surface-breaking defects. Internal defects need X-ray, CT or ultrasonic testing.
  • AI visual inspection lets plants check surface defects and dimensions on 100% of parts at cycle time, instead of sampling.

What Are Casting Defects?

A casting defect is any unwanted irregularity in a cast part that forms during pouring, solidification or cooling. Defects range from cosmetic marks to cracks and voids that make a part unsafe to machine or use.

For automotive and industrial parts housings, brackets, blocks, pump bodies a defect caught at the casting stage costs far less than one found after machining, assembly or in the field. That is why Level 1, Cast & Forged, is the first quality gate in the manufacturing chain.

Types of Casting Defects

Casting defects fall into five broad groups: gas defects, shrinkage defects, pouring defects, mould and core defects, and metallurgical defects. The table lists the 12 seen most often on the shop floor.

DefectWhat it looks likeCommon causesSeen on surface?
Gas porosityClusters of small rounded holesDissolved gas, moisture in sand or coresSometimes
BlowholesLarger smooth-walled cavitiesTrapped gas, poor mould ventingSometimes
PinholesTiny holes just under or at the surfaceHydrogen pickup, damp mouldsYes
Shrinkage cavityRough, jagged voids, often in thick sectionsPoor feeding, wrong riser designSometimes
Cold shutA line or seam where two metal streams failed to fuseLow pouring temperature, slow pouringYes
MisrunIncomplete part — thin sections not filledLow fluidity, thin walls, slow pourYes
Hot tearRagged crack, usually at section changesRestrained contraction during coolingYes
Sand inclusionEmbedded sand grains or rough patchesWeak mould, erosion by metal flowYes
Slag inclusionNon-metallic particles in or on the castingPoor skimming, turbulent pouringSometimes
Flash / finsThin unwanted metal at parting linesWorn patterns, poor mould closureYes
Mould shift / mismatchHalves of the part offset at the parting lineMisaligned cope and drag, worn pinsYes
Scab / swellRaised rough patch or bulge on the surfaceSand expansion, low mould hardnessYes

Common Forging Defects

Forging defects form while metal is shaped under heat and pressure. They usually trace back to die condition, billet temperature or material flow.

  • Laps and folds: metal folds over itself and leaves a surface seam.
  • Underfill: the die cavity is not completely filled, leaving missing features.
  • Die shift: upper and lower die halves misalign, offsetting the part.
  • Surface cracks: caused by forging at too low a temperature or by stressed material.
  • Scale pits: oxide scale pressed into the surface, leaving shallow pits.
  • Excess flash: too much material squeezed out at the parting line.
  • Internal bursts: cracks inside the part, invisible from outside.

Casting Defects and Remedies

Most casting defects come from a small set of process causes. Fix the cause, and a whole family of defects drops.

Root causeDefects it createsRemedy
Gas and moisturePorosity, blowholes, pinholesDry sand and cores, degas the melt, improve mould venting
Metal temperatureCold shuts, misrunsRaise pouring temperature, pour faster, shorten flow paths
Feeding and solidificationShrinkage cavities, hot tearsRedesign risers, add chills, avoid sharp section changes
Mould and core qualitySand inclusions, scabs, swellsIncrease mould strength, control sand properties, apply coatings
Tooling and alignmentFlash, mould shift, mismatchMaintain patterns and pins, check cope-drag alignment
Melt cleanlinessSlag inclusionsSkim properly, use filters, reduce turbulence in the gating

Remedies only work when you know which defect is rising and when. That needs consistent inspection data from every part, not a weekly sample.

Which Defects Can Visual Inspection Catch?

Visual inspection human or AI can only see what reaches the surface. This is the most important point to understand before choosing an inspection method.

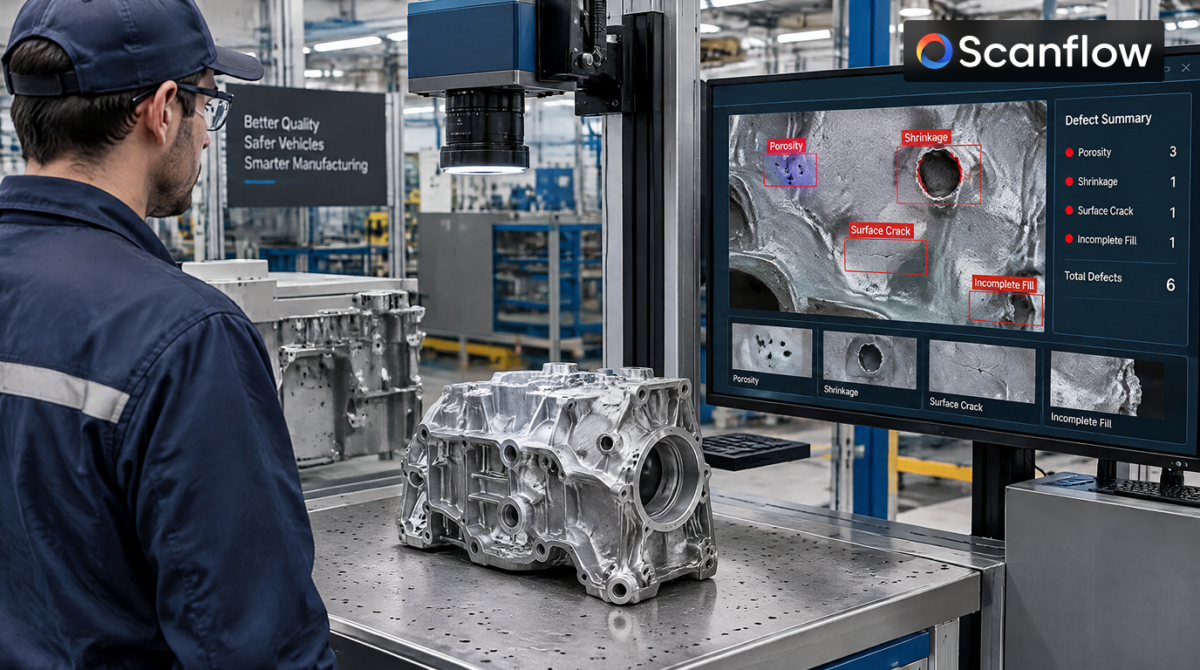
  • Optical inspection catches: cold shuts, misruns, hot tears, surface cracks, surface porosity and pinholes, sand inclusions, scabs, flash, mismatch, laps, underfill and scale pits.
  • Optical inspection cannot catch: internal porosity, sub-surface shrinkage, internal bursts or hidden inclusions. These need X-ray, CT or ultrasonic testing.

In practice, most plants combine both: radiography on a sample or on critical parts, and visual inspection on every part. The surface-visible defects are also the most frequent and the ones that slip through when manual inspectors are rushed.

Why Manual Inspection Misses Defects

Manual visual inspection is still standard at the casting stage. It struggles for three reasons:

  1. Fatigue. Attention drops across a shift. Small cracks and cold shuts are the first to be missed.
  2. Inconsistency. Two inspectors judge the same part differently. Acceptance criteria drift between shifts.
  3. Sampling. At high volumes, plants check a sample, not every part. Defects between samples reach machining.

The result is defects discovered late at machining, at assembly, or by the customer when the cost of each defect is many times higher.


How AI Visual Inspection Works for Cast and Forged Parts

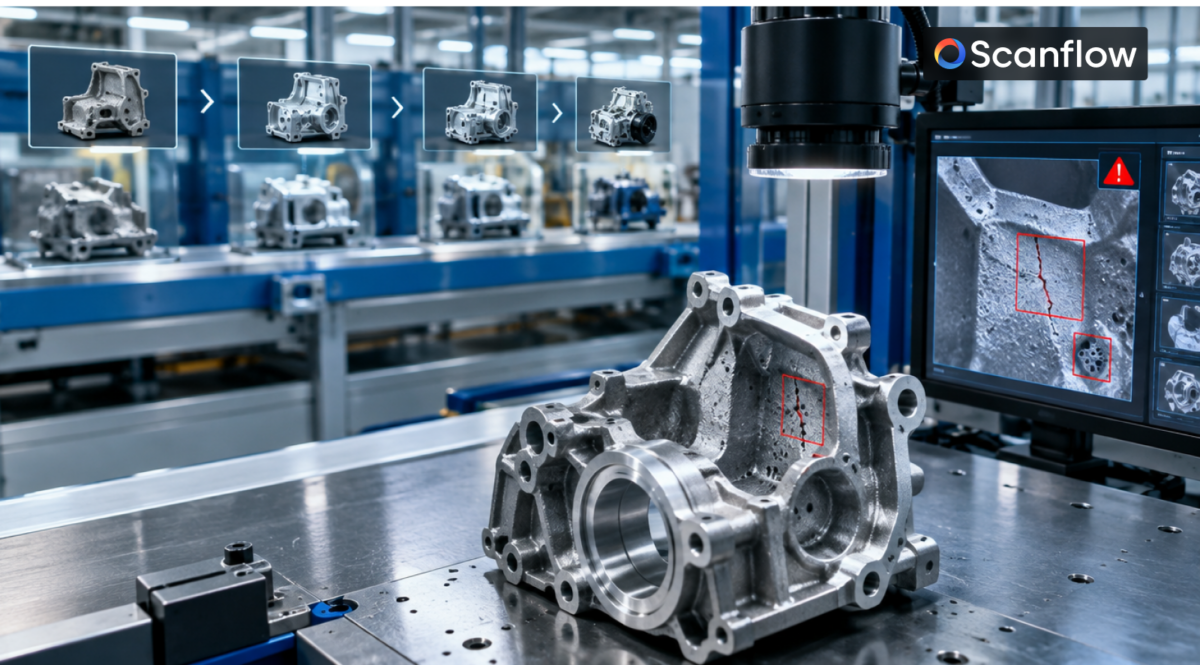
AI visual inspection uses cameras and trained deep-learning models to check every part at line speed, against the same criteria every time. Scanflow Inspect runs five checks on cast and forged parts:

Inspect checkWhat it does at Level 1
Surface DefectsFlags cracks, cold shuts, porosity, inclusions, flash and other surface-visible defects
Dimensional MeasurementMeasures critical dimensions and mismatch before parts move to machining
OCRReads cast-in or stamped heat, batch and part codes for traceability
Presence & AbsenceConfirms features, holes and cored openings are present
Orientation & AlignmentVerifies the part is correctly positioned for the next operation

Three things matter for a plant evaluating this:

  • Appliance included. Always. Inspect ships as a Ready Appliance camera, lighting, compute and software together so there is no separate hardware sourcing.
  • Defects and dimensions on one platform. One station replaces separate visual and gauging checks.
  • Validated, not assumed. Measurement capability is validated characteristic by characteristic using gauge R&R and MSA during the pilot.

As part of Scanflow’s five-level approach Cast & Forged, Machined & Finished, Sub-assemblies, Systems and Vehicle & Machine Level 1 is where catching a defect saves the most downstream cost.

Categories
Text Scanning

How Fleet Managers Can Audit Hundreds of Vehicles a Day by Scanning VINs on a Phone

Picture a fleet yard at seven in the morning. Trucks are lined up, drivers are waiting to leave and someone with a clipboard is walking the row, checking tires copying down numbers and ticking boxes. By ten o’clock that person has covered maybe forty vehicles, and half the notes will have to be typed into a system later. Multiply that by a yard with several hundred vehicles and the math stops working. Audits either get rushed, or they get skipped. 

The good news is that most fleets already own the only device they need. A modern smartphone camera, paired with the right software, can read vehicle and tire identifiers in seconds and send the results straight to the system the fleet already uses. This blog looks at why manual audits break down at scale, what a phone-based audit actually looks like, and what fleet managers should check before they switch. 

Why Manual Fleet Audits Break Down 

Fleet maintenance teams have always relied on a mix of clipboards, barcode stickers, and spreadsheets to track vehicles and tires. It works when the fleet is small. It stops working when the fleet grows, because every manual step adds time and every typed character adds a chance of error. 

The errors are usually small. A digit gets swapped in a VIN. A tire code is copied from a worn sidewall and one character is guessed. A vehicle gets logged against the wrong unit number. None of these mistakes is dramatic, but each one leaves a record that does not match reality and those mismatches only show up later, during a warranty claim, a recall, or a compliance check. 

There is also the time problem. A careful manual check of every tire on a vehicle can take several minutes. Across hundreds of vehicles, that is a full team working all day and it still leaves gaps. Many fleets end up checking only a sample, which means problems on the unchecked vehicles go unnoticed until something fails. 

What a Phone-Based Audit Looks Like 

A phone-based audit replaces typing with scanning. The person doing the audit walks up to the vehicle, points the phone camera at the identifier and the software reads it. VIN scanning captures the 17-character code from a dashboard plate, door frame, or chassis. The same approach reads license plates, so the vehicle is identified without anyone typing a registration number. 

For tires, the app reads the DOT codes and other sidewall markings directly from the camera image. Scanflow’s own materials describe fleet operators using mobile apps to run rapid tire audits, scanning every tire on every vehicle during routine maintenance instead of copying numbers by hand. Because the phone reads the same fields in the same way each time, the results do not depend on who happens to be holding it. 

No Special Equipment Needed 

One reason this approach scales is cost and simplicity. The scanning runs on phones the team already has, without dedicated hardware to buy, install, or maintain. A fleet can start with a few devices and add more as it grows. Several people can audit different vehicles at the same time, which is how a yard moves from dozens of vehicles a day to hundreds. The speed comes from many people working in parallel, each one spending seconds per scan rather than minutes per vehicle. 

Working Where Signal Is Weak 

Fleet yards, depots and roadside inspection points are not always places with strong internet. A tool that needs a constant connection will stall exactly when the team is busiest. That is why on-device processing matters. When VIN data is scanned and inferred on-device, the audit keeps moving even when the signal drops and the records sync once the phone is back online. The team does not have to wait or redo work. 

From Scan to System 

A scan is only useful if the data goes somewhere. The strongest tools return structured vehicle identity data, such as make, model, and year, that can be pushed into the systems a fleet already runs. Through fleet management API integration, the information flows into the maintenance platform or records system automatically, without anyone re-keying it. That removes the second round of typing that causes so many errors in the first place. 

This also changes what reports look like. When every scan is timestamped and tied to a specific vehicle and tire, tire inspection compliance reports can be produced from the data directly, instead of being assembled by hand at the end of the month. A manager can see which vehicles were checked, when and what was found. 

What This Means for Downtime 

The practical payoff for most fleets is fewer surprises. When tire condition and age are checked on every vehicle, not just a sample, issues are found while they are still cheap to fix. A worn tire gets replaced during scheduled maintenance rather than after a roadside failure. That is how better auditing helps reduce fleet downtime: not by removing problems, but by finding them early and on the fleet’s own schedule. 

Records matter after the fact too. Scanflow’s materials cite figures showing that retailers and fleets with verified tire installation records, including the DOT code, date, mileage and vehicle VIN, see noticeably higher warranty claim acceptance than those with incomplete ones. Treat that number as a vendor claim worth testing in your own operation, but the logic holds: a claim backed by a clean record is easier to approve than one backed by a guess. 

Recalls are the other case. When a recall lists specific tire codes, a fleet with scanned, searchable records can find the affected tires in minutes. A fleet relying on paper notes has to inspect them by hand. 

Traceability and Compliance Without the Paperwork 

Underneath all of this is a simple idea: every vehicle and tire should carry a record that is accurate from the moment it is captured. Fast, accurate traceability and compliance is hard to achieve when records are typed by hand, and much easier when they are created automatically at the point of scanning. For fleets that answer to customers, insurers, or regulators, that automatic record is what turns an audit from a chore into evidence. 

What to Check Before Switching 

Not every tool will perform the same on a real yard. A few questions are worth asking. Does it read reliably on dirty, worn, or faded markings and in poor light, not just on clean demo samples? Does it work offline? Does it connect to the systems you already use, or does it create a new silo? And can you test it on your own vehicles before committing? A short pilot on a single yard will tell you more than any brochure. 

It also helps to decide up front who owns the process. The best results usually come when one person is responsible for how scans are done, where the data goes and who reviews the reports. Without that, even a good tool ends up used differently by every shift. A simple written routine, such as which identifiers to scan at check-in and which to scan during maintenance, keeps the records consistent and makes the numbers easy to trust. 

So, Can One Phone Really Do This? 

One phone will not audit a whole fleet alone. But a handful of phones, in the hands of a normal maintenance team, can cover far more vehicles per day than clipboards ever could, with fewer errors and records that are ready to use. For fleet managers tired of choosing between thorough audits and fast ones, that is a trade worth looking at closely.
 

#FleetManagement #FleetMaintenance #VINScanning #TireInspection #TireTraceability #AutomotiveAI #ComputerVision #MobileScanning #DOTCode #FleetOperations #Logistics #SupplyChain #AssetIdentification #Traceability #ReduceDowntime #DigitalTransformation #B2B #SmartScanning #FleetTech #Compliance 

Categories
Quality control

Why Do Casting Defects Cost More the Later They’re Found? 

This escalating cost curve isn’t a theory, it’s one of the most consistent patterns in manufacturing quality economics and it applies with particular force to castings, where defects like porosity, cold shuts and shrinkage are often invisible until later processing steps expose them. Understanding why the cost multiplies at each stage, rather than staying flat, is what actually justifies investing in earlier, more thorough inspection instead of treating it as an optional expense. 

The Value-Added Trap 

The core mechanic driving this cost curve is simple: every processing step adds value to a part, and a defect discovered after that value has been added means the added value is lost along with the original material. A raw casting with a hidden porosity defect represents the cost of metal, energy and mold preparation. Once that casting goes through machining, drilling, tapping, and precision finishing, it now represents all of that original cost plus the labor, tooling wear and machine time invested in every subsequent operation. If the defect is caught at this later stage, all of that added value is lost at once, not just the original casting cost. 

This is precisely why in-line quality control positioned as early as possible in the production sequence delivers outsized returns relative to its cost. Catching a defect immediately after casting, before any further value gets added, caps the loss at the earliest and cheapest possible point. Catching the same defect three or four processing steps later doesn’t just cost more, it costs more by a multiple that grows with every step in between. 

Why Some Defects Only Become Visible Later 

Part of what makes this problem particularly stubborn in casting operations specifically is that certain defects are genuinely difficult to detect until later processing exposes them. Porosity beneath a surface that hasn’t been machined yet may be completely invisible to visual inspection. A shrinkage cavity near a core print might only become apparent once machining removes enough material to expose it. This is exactly the gap that real-time defect detection using computer vision aims to close, catching surface-level indicators and subtle irregularities that correlate with these hidden defects, at a much earlier point than waiting for machining to reveal them by accident. 

Complex casting geometries, cored passages, undercuts and curved surfaces, make this detection problem harder, not easier. A defect hidden in a hard-to-see recess is exactly the kind of thing a single-angle inspection setup is likely to miss, which is why multi-angle capture matters specifically for castings with intricate geometry rather than simple, flat parts where a single camera view is sufficient. 

Quantifying the Multiplier: What “Later” Actually Costs 

Manufacturing quality frameworks have quantified this escalation for decades under different names, but the underlying pattern holds consistently across industries: a defect caught during in-process inspection costs meaningfully less than the same defect caught during final inspection, which in turn costs meaningfully less than a defect that reaches a customer and triggers a field failure or warranty claim. For castings specifically, where individual components often get assembled into larger, more expensive finished goods, the multiplier at the customer stage can be dramatic, not just the cost of the casting and its downstream processing, but the cost of the entire assembly it was part of, plus logistics, plus the OEM compliance and corrective action documentation a customer will demand before continuing the relationship. 

This is the argument that finance teams evaluating an inspection investment often miss when they compare the cost of a quality control system against the cost of the scrap it catches at its own stage. The real comparison isn’t “cost of the system versus cost of scrap caught here.” It’s “cost of the system versus the cost of scrap caught here, plus every downstream defect it prevents from reaching a far more expensive later stage instead.” 

Why Audit-Ready Records Matter to This Calculation Too 

There’s a second, less obvious cost multiplier tied to when a defect is found: how difficult it is to trace the cause. A defect caught immediately, with an image-tagged inspection record showing exactly which part, which batch, and which production conditions were involved, gives a quality team a clear, immediate path to root cause analysis. A defect discovered weeks later, after the part has moved through multiple stages and the specific production conditions have been forgotten or never recorded, turns root cause investigation into guesswork. 

Audit-ready logs generated automatically at the point of inspection solve this by preserving the exact context a defect occurred in, rather than relying on someone’s memory of a shift that happened weeks earlier. This matters because a defect caught late isn’t just expensive in scrap and rework, it’s also harder to prevent from recurring, since the evidence needed to identify its root cause has usually degraded by the time anyone investigates it. 

What This Means for How Foundries Should Prioritize Inspection 

The practical takeaway isn’t that final inspection is worthless, it still matters as a last line of defense. It’s that inspection investment delivers the highest return when it’s positioned as early in the process as possible, ideally immediately after casting and before any significant value-adding steps occur. A foundry that concentrates inspection effort at final QC, while leaving in-process stages largely unchecked, is structurally guaranteeing that any defects that do slip through will be found at the most expensive possible point rather than the cheapest one. 

This reframes quality control spending as a timing decision as much as a detection-accuracy decision. A system that catches 90 percent of defects immediately after casting is often more valuable, financially, than a system that catches 98 percent of defects only at final inspection, because of how dramatically the cost of each remaining defect grows across the intervening steps. 

It’s a useful exercise for any foundry to map out its own value-added stages explicitly, from raw casting through machining, coating, assembly, and shipment, and estimate the cumulative cost added at each one. That exercise alone often reveals how much more a defect costs to catch at the current inspection point compared to the earliest possible one, an argument that tends to land more effectively with finance stakeholders than an abstract discussion of detection accuracy percentages. 

So, Why Does Timing Matter So Much? 

The honest answer is that a casting defect doesn’t have a fixed cost. It has a cost that grows with every step of value added before it’s caught, every hour of investigation required to trace it back to its cause, and every stage of a customer relationship it manages to survive before finally surfacing. The foundries getting real value from AI-based visual inspection aren’t just catching more defects. They’re catching them earlier, at the point in the process where the same defect costs the least to correct and the least to prevent from happening again. 

Categories
ITAD

What Really Happens to Your Old Company Laptops After You Throw Them Away

“Throw them away” is rarely literal. Very few organizations actually send retired laptops to a landfill anymore, most have some kind of disposal or recycling arrangement in place. The more accurate and more uncomfortable question is what happens in between: who actually handles the device, what happens to the data still on it, and whether anyone can prove, with real documentation, what that process actually looked like for any specific machine.

The Journey Most People Never See

A retired laptop typically moves through several hands before its story ends. It gets pulled from a desk or shipped back from a remote employee, logged by IT or handed to a facilities team, boxed with a batch of other retired devices, and eventually picked up by a disposition vendor. At each of these handoffs, the device is supposed to be tracked, but in a large number of organizations, that tracking still depends on someone manually writing down a serial number or asset tag, correctly, under time pressure, in the middle of an otherwise busy day.

This is exactly where things go wrong, and it’s rarely intentional or careless. A serial number gets mistyped. A label is smudged or partially peeled off and gets guessed at. A device gets logged under the wrong department or client account during a high-volume intake day. The laptop itself is fine, physically accounted for and processed like every other device, but the digital record no longer matches reality. In the ITAD industry, this mismatch has a name: a ghost asset, a device that exists physically but whose paper trail has quietly diverged from the truth.

Why This Matters Far More Than It Sounds

A ghost asset sounds like a minor administrative inconvenience until you consider what’s actually on a typical company laptop. Client records, internal financial data, saved credentials, years of email history, sometimes personal data covered by privacy regulations. The entire point of a proper IT asset disposition process is being able to prove, specifically, what happened to that data and that device. If the tracking record doesn’t reliably match the physical device, that proof becomes far weaker exactly when it matters most, during a compliance audit, a customer security review, or the aftermath of a data breach where a specific device’s fate needs to be reconstructed with confidence.

This is also where the difference between “we recycled it responsibly” and “we can prove what happened to it” becomes financially significant. Regulators and enterprise customers increasingly don’t accept the first claim without the second. A business that hands over retired laptops to a vendor without demanding a real chain of custody is trusting that nothing goes wrong, rather than being able to demonstrate that nothing did.

What Actually Happens to the Data

Before a laptop is resold, recycled, or scrapped, its storage drive needs to go through certified data destruction, a documented process that renders data on the drive permanently unrecoverable, distinct from simply deleting files or performing a factory reset, neither of which actually removes data at the level required for a device holding sensitive information. This step should generate its own record: which device, which drive, what method was used, and when it happened.

The uncomfortable reality is that many organizations never actually verify this step happened for a specific machine. They trust that their vendor handled it, without ever seeing documentation tied to that exact laptop, that exact serial number, that exact date. If a data exposure incident later traces back to a retired device, “we assumed our vendor handled it” is a considerably weaker position than being able to produce a certificate showing precisely when and how that device’s data was destroyed.

This is a more common gap than most IT leaders assume. It’s easy to sign a service agreement that mentions certified destruction and consider the requirement satisfied. It’s a very different thing to be able to pull up the specific certificate for a specific laptop, six months after the fact, when a customer or regulator asks for it directly. The first is a policy on paper. The second is proof, and only one of them actually holds up under scrutiny.

What Happens to the Hardware Itself

Assuming data destruction is handled properly, the physical laptop still has a second, separate story: what happens to the hardware. A retired laptop that’s still functional often has real resale value through remarketing and refurbishment, value that’s completely lost if the device goes straight into a recycling stream without ever being evaluated for resale. Businesses that never ask this question are frequently leaving recoverable value on the table with every refresh cycle, treating a resalable asset the same way they’d treat genuine scrap.

The businesses getting real value from this process aren’t necessarily doing anything exotic. They’re simply demanding visibility: which devices were resold, which were recycled, and what the actual financial return was, rather than accepting a vague assurance that everything was “handled responsibly.”

It’s worth noting that this isn’t purely a sustainability talking point either. Recovered value from remarketed laptops can be reinvested directly into the next hardware refresh, effectively lowering the real cost of every future purchase cycle. Businesses that treat retired hardware purely as a disposal problem are missing a recurring, entirely legitimate source of budget relief that shows up every single time a fleet of devices is retired.

The Documentation Gap Is the Real Problem

Underneath every one of these issues, ghost assets, unverified data destruction, unclear disposition outcomes, is the same root cause: a documentation gap created by manual tracking. Modern automated device identification closes this gap by capturing serial numbers, asset tags, and device details through scanning rather than manual transcription, creating a tamper-proof, timestamped record from the moment a device enters the disposition process through its final outcome. That record becomes the chain of custody a business can actually produce when someone asks the hard question: what happened to this specific laptop, and can you prove it?

Audit-ready documentation generated this way isn’t reconstructed after the fact from scattered spreadsheets. It exists automatically, tied to the device from intake onward, which is precisely what a business needs when a regulator, a customer, or an internal audit eventually asks for it.

So, What Really Happens to Your Old Laptops?

The honest answer, for a large number of organizations, is: nobody can say with complete certainty. The device left a desk, went through a process assumed to be handled correctly, and somewhere along the way, the paper trail may or may not have stayed accurate. That uncertainty is the actual product being sold by “responsible disposal,” not proof, just an assumption that things went the way they were supposed to.

The businesses that have actually closed this gap aren’t relying on trust in a vendor’s good intentions. They’re relying on documented, traceable records generated automatically at every step, from the moment a laptop leaves a desk to the moment its data is certified destroyed and its hardware finds its final disposition. Everyone else is still hoping the story their vendor tells matches what actually happened to a specific machine, without any real way to check.

Categories
Tire Sidewall

Are Tire Manufacturers Losing Millions Because of Poor Traceability Without Realizing It?

Every tire manufactured today carries a unique identity on its sidewall: a DOT code, a serial number, batch and compound information, manufacturer data. In theory, that identity should follow the tire through its entire life, from the production line to the warehouse, through distribution, to the retailer, and into a vehicle. In practice, at nearly every one of those handoffs, the process depends on someone manually reading and re-entering that sidewall data, and manual entry is exactly where traceability quietly breaks down. 

The Hidden Cost Hiding in Manual Data Entry 

Manual reading of DOT codes and tire sizes during receiving and order picking carries error rates commonly in the 2 to 5 percent range. On a shipment of a thousand tires, that’s 20 to 50 tires logged incorrectly, each one a potential mis-ship, an inventory discrepancy, or a record that no longer matches the physical tire it’s supposed to represent. Multiply that across the volume a mid-size tire manufacturer or distributor moves in a single month, and the numbers stop looking like rounding errors and start looking like a real, ongoing cost. 

This isn’t a one-time cost either. Every mis-logged tire creates downstream work: someone has to notice the discrepancy, investigate it, correct the record and in some cases physically locate a tire that’s been placed in the wrong bin or shipped to the wrong customer. None of that labor shows up as a line item called “traceability cost.” It gets absorbed into general warehouse labor, customer service time, and inventory shrinkage, which is exactly why the true cost stays invisible even to companies tracking their numbers closely. 

It’s worth being specific about where this compounds fastest: high-turnover distribution centers processing thousands of tires weekly, where even a small error rate translates into a steady stream of discrepancies that staff treat as routine, rather than as a symptom of a process that was never built to scale accurately in the first place. A single misread code is a minor inconvenience. Thousands of them, month after month, are an operating cost with no name and no owner. 

Where the Losses Compound: Warranty and Recall Exposure 

The cost of poor traceability gets significantly more serious once a tire leaves the factory. When a customer buys tires, the retailer is supposed to log the DOT code for warranty registration and recall tracking. In practice, many retailers skip this step because manual entry is too slow during busy service appointments and the result is a tire installed on a vehicle with no traceability of that installation ever having been recorded. 

This becomes an expensive problem the moment a recall is issued. A manufacturer that can trace exactly which batches, which production windows, and which distribution channels a defective compound or tooling issue affected can execute a targeted, contained recall. A manufacturer relying on incomplete installation records has to cast a far wider net, often recalling more tires than were actually affected, simply because the data needed to narrow the scope was never captured accurately in the first place. That gap between a targeted recall and an overly broad one translates directly into unnecessary replacement costs, logistics expense, and reputational exposure that a manufacturer with strong tire manufacturing traceability would never have had to absorb. 

Fleet and Warehouse Operations Feel This Daily, Not Just During a Recall 

Recalls are the dramatic case, but the day-to-day cost is arguably larger in aggregate. Fleet operators tracking thousands of tires across hundreds of vehicles frequently rely on manual inspections and spreadsheet records to manage rotation schedules, replacement timing, and warranty claims. Every manual entry in that process is another opportunity for a transposed digit or a misread code to quietly corrupt the underlying data, and those errors compound over months into replacement schedules built on inaccurate information. 

Warehouse and distribution operations face the same exposure at a larger scale. Without real-time asset identification at receiving, inventory counts drift further from reality with every shipment processed manually and reconciling that drift consumes staff time that never shows up as a traceability cost on any budget line, even though that’s exactly what it is. 

What Automated Sidewall Scanning Actually Changes 

The fix isn’t complicated in concept, even if it requires a real operational shift. Vision-based scanning systems can automatically capture DOT codes, serial numbers, batch identifiers, and other sidewall data as tires pass through quality control stations, warehouse receiving, or distribution checkpoints, creating a verified digital record without manual data entry at any of those steps. Because every tire becomes a digitally traceable asset from the point of manufacture onward, the chain of custody that manual processes struggle to maintain gets built in automatically instead. 

This matters most at the exact moments where manual processes fail hardest: high-volume receiving, busy retail service counters, and large-scale recall response. Audit-ready logs generated automatically at each scan point mean a manufacturer or distributor can answer exactly which tires are affected by an issue, where they currently are, and what their full history looks like, without reconstructing that picture from incomplete paper trails after the fact. 

The Real Question for Manufacturers to Ask 

Most tire manufacturers have never actually calculated what poor traceability costs them, because the expense is scattered across so many different departments that it never gets aggregated into a single number. The honest exercise worth running is adding up mis-ship rates, warranty dispute resolution time, recall scope and cost history, and inventory reconciliation labor, then asking how much of that total traces back to a sidewall code that was never captured accurately in the first place. 

It’s also worth asking a harder follow-up question: how would this business even know if it improved? Without a baseline measurement of current error rates, mis-ship frequency, and reconciliation hours, there’s no way to demonstrate the return on fixing the problem, which is part of why traceability investment gets deprioritized in favor of costs that are easier to point to on a spreadsheet. Establishing that baseline, even roughly, is often the step that turns traceability from an abstract concern into a funded project. 

So, Are Tire Manufacturers Losing Millions Without Realizing It? 

For most manufacturers still relying on manual data entry at key points in the supply chain, the honest answer is very likely yes. The losses rarely show up as a single, obvious number. They’re distributed across mis-ships, warranty disputes, oversized recalls, and warehouse reconciliation work, each one small enough on its own to be written off as a cost of doing business. Added together across a year of production and distribution volume, they represent exactly the kind of expense that automated, traceable sidewall scanning was built to eliminate. The manufacturers who’ve made that connection aren’t just running a tighter operation. They’ve found a cost that was hiding in plain sight the entire time.